
Product Feeds for Ecommerce: Why Your Catalogue Must Be Understandable to More Than Shoppers
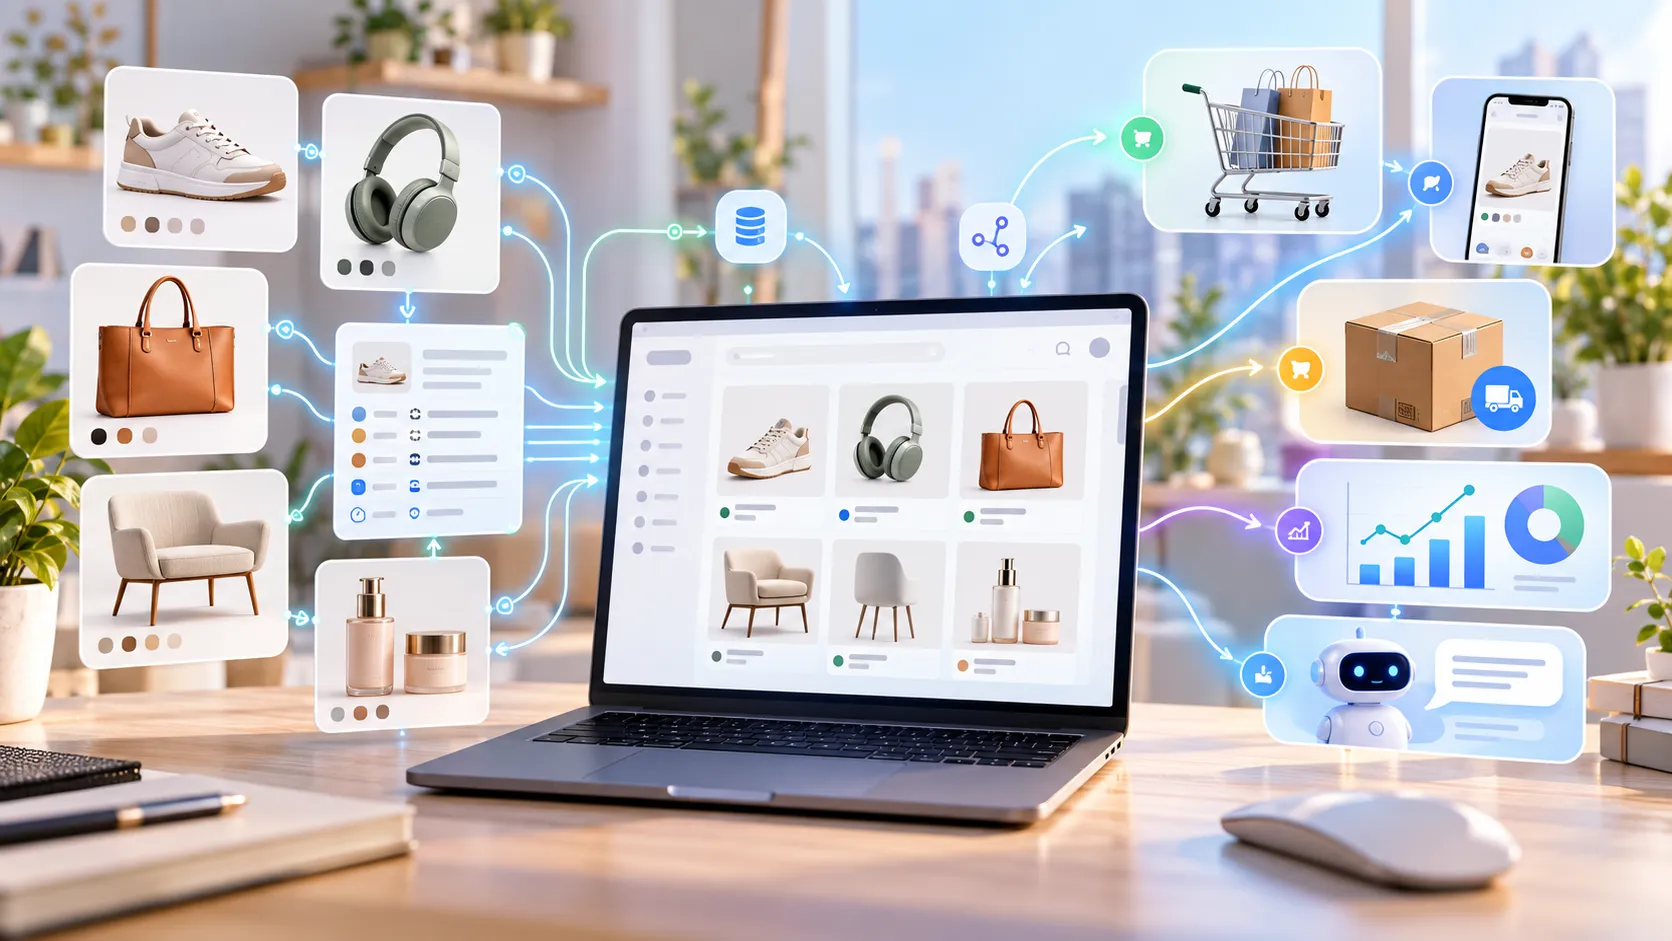
For years, an ecommerce catalogue was built mainly for two audiences: shoppers and search engines.
Customers needed clear product names, images, specifications, prices and availability.
Search engines needed pages they could crawl and index.
In 2026, that is no longer enough.
Between an online store and the customer there are now many more systems:
shopping platforms, marketplaces, advertising networks, comparison engines, mobile applications, recommendation systems and AI shopping assistants.
All of them need product data.
Not just an attractive product page.
Not a promotional banner.
They need structured information:
What is this product? How much does it cost? Is it available? What category does it belong to? What are its attributes? Where can it be purchased?
One of the main ways to provide that information is through a product feed.
And product feeds are gradually becoming much more than a technical file created for advertising.
They are becoming part of the core infrastructure of modern ecommerce.
What is a product feed?
A product feed is a structured file or data stream containing information about products in an online store.
The simplest way to think about it is as a catalogue designed for machines rather than people.
A product feed may contain:
product ID;
title;
description;
category;
brand;
SKU;
GTIN or EAN;
price;
sale price;
currency;
availability;
stock quantity;
product URL;
image URLs;
product attributes;
variants;
shipping information.
The exact fields depend on the platform receiving the data.
Google Merchant Center, marketplaces, comparison shopping engines and advertising platforms all have their own requirements.
Some systems accept XML.
Others use CSV, TSV, JSON or API connections.
The important point is this:
a product feed is not one specific file format. It is a method of continuously passing structured catalogue data from one system to another.
Why use a feed if products already exist on the website?
This is a reasonable question.
Every product already has a page.
The title is there.
The image is there.
The price is visible.
Why can an external platform not simply open the page and read the information?
It can.
Search engines have been doing exactly that for years.
But there is an important difference between crawling a page and receiving structured product data directly.
Imagine that a product costs €129 in the morning and is reduced to €109 in the afternoon.
The website updates immediately.
A search engine may revisit the page hours or days later.
A product feed, however, can be regenerated and submitted much more frequently.
The same problem applies to stock.
A product sells out.
An external shopping platform still shows it as available.
A customer clicks through and discovers:
Out of stock.
That is a bad customer experience and a wasted visit.
The purpose of a product feed is therefore not simply to list products.
It is to help external channels stay synchronised with the actual state of the catalogue.
Where product feeds are used
Product feeds are often associated with advertising platforms.
But their role is much broader.
They can power:
Google Shopping;
marketplaces;
price comparison services;
dynamic advertising;
affiliate networks;
shopping search engines;
mobile apps;
recommendation systems;
social commerce;
AI shopping services.
One ecommerce catalogue can therefore become the data source for many different sales channels.
This changes how retailers should think about product data.
A catalogue is no longer simply a collection of pages on a website.
It is a structured product database from which many different customer experiences can be generated.
Google is one of the most obvious examples
For European retailers, Google Merchant Center is one of the clearest examples of why structured product feeds matter.
Merchants can provide data such as:
product title;
price;
availability;
brand;
GTIN;
images;
product condition;
shipping information.
Google can then use those data across shopping-related experiences.
The important lesson is not that every store must optimise only for Google.
The broader lesson is that major commerce platforms increasingly prefer predictable, structured product information.
This is much more reliable than trying to infer everything from visual page content.
Product feeds and Schema.org are not competitors
Retailers sometimes treat structured data and feeds as alternatives.
They are not.
They solve different problems.
Schema.org markup lives directly on the product page.
It helps search engines understand what the page represents.
A product feed sends catalogue information separately in a structured format.
A strong ecommerce setup can therefore use all three layers:
a high-quality product page;
structured Product markup;
an up-to-date product feed.
The information should agree across all of them.
If the website says €149, Schema.org says €139 and the feed says €159, adding more technologies has not improved the catalogue.
It has simply created three conflicting versions of the truth.
AI is becoming another consumer of product data
The most interesting change is happening outside traditional search.
A shopper increasingly does not need to begin with a product category or exact keyword.
They may ask:
“Find wireless headphones under €150 with strong noise cancellation and more than 30 hours of battery life.”
An AI system has to do more than find pages containing the phrase “wireless headphones”.
It needs to compare:
price;
product type;
specifications;
availability;
variants;
sellers.
This is where structured product information becomes extremely valuable.
AI-based product discovery is gradually creating another channel through which customers can find products.
That means retailers need to think not only about:
How does the product page look?
but also:
How clearly is this product represented as data?
A good feed starts before the XML file
One of the most common mistakes is assuming that a feed problem can be solved by installing a module that generates XML.
A feed generator cannot repair a poor catalogue.
If a product is called:
“Model 3482 Black”
then a very similar title will probably be exported.
If the brand exists only inside the product title rather than in a dedicated field, external systems may struggle to identify it reliably.
If colour exists only somewhere inside a long description, it cannot be used consistently as a structured attribute.
If variants are organised badly, that problem will simply be exported.
A feed reflects the quality of the source catalogue.
That is why feed optimisation does not begin with export settings.
It begins with product data architecture.
Every product needs a stable identifier
Product identifiers are one of the least glamorous but most important parts of ecommerce integration.
An online store already has internal product IDs.
When products are sent to external systems, those identifiers should remain stable.
If a product is exported today as:
1257
it should not unexpectedly become:
new-product-9834
tomorrow simply because the feed generation logic changed.
External systems use IDs to understand that the product is still the same item even when its price, stock or description changes.
Stable identifiers are especially important when the same catalogue is distributed across multiple channels.
They make synchronisation, analytics and updates far more reliable.
Product titles should describe the actual product
Online catalogues sometimes contain product titles such as:
“BESTSELLER!”
“New Arrival”
“Item 48292”
“Model No. 17”
Someone familiar with the internal catalogue may understand what these mean.
External systems do not.
A useful title identifies the product itself.
For example:
SoundPro X5 Wireless Noise-Cancelling Headphones, Black
is much clearer than:
SoundPro X5
This does not mean stuffing the title with every possible SEO keyword.
Product titles should remain readable.
But they should clearly communicate what is being sold.
Product attributes are becoming the machine language of ecommerce
Consider two descriptions.
The first says:
“A lightweight model with excellent battery life.”
The second contains separate attributes:
Weight: 245 g
Battery life: 32 hours
Bluetooth: 5.3
Active noise cancellation: Yes
Both can be useful to a human.
For automated processing, the second is much more valuable.
A system can compare a numeric value against a requirement.
A shopper may ask for:
“under 300 grams”
or:
“more than 24 hours of battery life.”
If these facts exist only inside marketing copy, they can still potentially be extracted, but the process becomes less reliable.
Structured attributes make product data easier to understand, compare and reuse.
Product variants need structure too
Size S and size XL are not completely different products.
A black smartphone and the same model in blue are variants of the same base product.
But variants may have different:
SKUs;
stock levels;
prices;
barcodes;
images;
availability.
External platforms need to understand those relationships.
If every variant is exported as an unrelated product, the catalogue may become filled with near-identical listings.
If variants are not exported at all, a platform may show the product as available even when the required size is sold out.
The way variants and combinations are structured inside the ecommerce platform therefore directly affects the quality of product feeds.
Pricing must match the store
One of the fastest ways to lose trust is showing one price externally and another after the customer clicks through.
For example:
A shopping platform shows €79.
The customer reaches the website.
The product now costs €89.
Even if this happened because the feed was not updated quickly enough, it feels misleading.
The feed therefore needs to use the same pricing logic as the store.
Special attention is required for:
sale prices;
variant pricing;
currencies;
taxes;
customer-specific prices;
promotional rules.
If an external channel cannot support a particular pricing model, the retailer needs clear rules for deciding which price should be exported.
Availability needs to reflect reality
The same applies to stock.
The store says the product is sold out.
The external platform says it is available.
A customer arrives and cannot purchase it.
With a large catalogue, this can affect hundreds or thousands of products.
For that reason, product feeds should usually be generated automatically from the current catalogue rather than maintained manually.
For stores with rapidly changing stock, feeds may need to be updated frequently or replaced by a more direct API integration.
Product images are data too
Images may look like a purely visual part of ecommerce.
In a product feed, however, they are usually transmitted as URLs.
The receiving platform must be able to access them reliably.
Common problems include:
the image requires authentication;
the file was deleted;
external requests are blocked;
only a low-resolution thumbnail is provided;
the wrong image is associated with a variant;
the URL is temporary and expires.
Image URLs should therefore be monitored just like price and stock.
This matters even more as visual search and multimodal AI become more common.
One source of truth is the key principle
The more channels an online store uses, the more dangerous it becomes to manage each one separately.
Imagine a catalogue with 25,000 products.
Prices exist in:
the website;
Google Merchant Center;
a marketplace;
an advertising platform;
a mobile app;
a comparison shopping engine.
If they are updated independently, inconsistencies are inevitable.
A better architecture has one primary source of product truth.
That could be the ecommerce platform itself or an ERP/PIM system connected to it.
Then the data flow looks something like:
Catalogue → product feed/API → external channels
or:
ERP/PIM → ecommerce platform → feeds and APIs → external channels
The price changes once.
Other channels receive the update automatically.
Product feeds matter even more for large catalogues
A store with 30 products can still check many things manually.
A store with 30,000 cannot.
And if each product has several combinations, the business may effectively be managing hundreds of thousands of individual sellable states.
Large catalogues depend on:
automated feed generation;
stable IDs;
consistent categories;
structured attributes;
brands;
variants;
error monitoring;
regular updates;
logging.
At that scale, a product feed becomes part of system architecture rather than a one-time marketing export.
Multilingual European catalogues add another challenge
European ecommerce often involves multiple countries and languages.
The same product may require:
English;
German;
French;
Italian;
Spanish;
Dutch;
and potentially many more versions.
The product itself has not changed.
But titles, descriptions and customer-facing attribute labels have.
This is why multilingual ecommerce needs a clean separation between underlying product meaning and translated presentation.
For example:
Colour
Farbe
Couleur
Colore
These are different labels for the same concept.
A good catalogue model should preserve that relationship.
Otherwise, every additional language can create another layer of duplicated attributes.
Cross-border commerce also introduces currency and tax complexity
A European retailer may sell the same product in euros, pounds sterling, Danish kroner or Swedish kronor.
VAT handling may also vary depending on the transaction and market.
That creates another requirement for product feeds:
the data sent externally must match the actual buying experience.
If a customer sees one currency in a shopping platform and another after clicking through, conversion can suffer.
The same applies to tax-inclusive and tax-exclusive prices.
External channels need a predictable representation of the final commercial offer.
How this works with PrestaShop
PrestaShop already stores much of the required catalogue information in structured form.
A product can contain:
title;
description;
price;
categories;
brand;
images;
features;
attributes;
combinations;
stock;
reference;
EAN/GTIN;
other identifiers.
That makes it a strong foundation for automated feed generation.
A module or integration can read the catalogue and transform the data into the format required by a particular channel.
For example:
XML;
CSV;
Google-compatible feeds;
marketplace feeds;
APIs;
custom partner formats.
There is no need to manually maintain a completely separate catalogue for every channel.
But automation does not mean “set it and forget it”
Product feeds still need monitoring.
Retailers should regularly check:
how many products are exported;
how many are rejected;
whether any products have missing images;
whether prices match;
whether products are missing categories;
whether attributes are disappearing;
whether variants are exported correctly;
whether scheduled feed generation is still running.
Sudden changes are particularly important.
Yesterday the feed contained 18,000 products.
Today it contains 2,300.
That should trigger an investigation immediately, not after customers begin reporting missing products.
How to audit your catalogue today
A useful first check does not require sophisticated tools.
Take ten different products.
Not the ten best-looking products.
Choose a mix:
a simple product;
a product with variants;
a discounted product;
an out-of-stock item;
a product with several images;
a product with many attributes.
Then check:
Does every product have a clear title?
Is the brand stored properly?
Is there a SKU or reference?
Are important specifications stored as structured attributes?
Are variants organised correctly?
Does the exported price match the website?
Is availability accurate?
Do image URLs work directly?
Is the category correct?
Does the product ID remain stable?
If obvious problems appear in a sample of ten items, they will almost certainly scale across a catalogue containing thousands.
Clean product data is becoming a competitive advantage
For a long time, product data was treated mainly as a technical concern.
The product page simply had to look good.
That model is changing.
The same catalogue is now consumed by more and more systems:
search engines;
advertising platforms;
marketplaces;
mobile apps;
recommendation engines;
visual search;
AI assistants.
The cleaner the underlying data, the easier it becomes to connect new channels.
The opposite is also true.
A chaotic catalogue turns every new integration into another data-cleaning project.
How this connects to Ewonta
Ewonta stores are based on PrestaShop, so the catalogue remains a structured part of the ecommerce platform rather than a collection of visual blocks inside a closed website builder.
Products, categories, features, combinations, images, prices and stock can therefore be used not only on the storefront but also by external integrations.
This matters especially for businesses operating across several channels:
their own online store;
marketplaces;
mobile applications;
ERP or warehouse systems;
shopping platforms;
AI-based tools.
In this architecture, the website is not an isolated storefront.
It becomes part of a wider product-data infrastructure.
What has actually changed
Product feeds are not new.
XML feeds existed long before AI shopping.
The real change is the number of systems that now depend on ecommerce product data.
In the past, a retailer might think:
“We need a feed for advertising.”
A better way to think about it now is:
“We need a high-quality catalogue that can be distributed to any sales channel.”
Today that channel may be Google Shopping.
Tomorrow it may be a marketplace.
Then a mobile app.
After that, an AI shopping assistant.
If every new channel requires the retailer to rebuild or manually clean the catalogue, the real problem is not the channel.
The problem is the underlying data.
That is why one of the most important technical assets of a modern online store is no longer just its design or search rankings.
It is a clean, structured and continuously updated product catalogue that can be understood equally well by customers, search engines and machines.